12. Functions, Layers, Handlers, and Caching
Copying a useful node network creates a maintenance question: may the copies diverge, or must they stay identical? If they must stay identical, make them a function.
An explicit cache policy can also reuse a function’s previous result. An ordinary visual group has no such call contract.
These constructs may look similar on a canvas, but serve different jobs:
| Construct | What it gives the Flow |
|---|---|
| Layer | A nested visual region that keeps one graph readable |
| Function | A reusable typed boundary inside the same Flow |
| Handler/Event | A triggerable boundary that a caller or agent can invoke |
| Function cache | An authored promise that a previous output may replace the entire call |
Release check: FlowScript functions become Function layers with typed boundary pins. Their purity follows the structure of their contents; each node designer declares node purity through the presence or absence of Execution pins. Any user function with a parameter can be called as a method on its first argument.
@cacheis explicit and may be attached to an impure function; a hit skips the whole body. Cache keys omit the function body, package versions, global and runtime variables, model choice, and external state unless those dependencies become inputs. A Function layer cannot yet be registered directly as an agent tool. It needs a referenceable Event handler; the planned automatic shim is not implemented.
12.1 A function is a reusable layer contract
Section titled “12.1 A function is a reusable layer contract”A FlowScript function gives a node network a name, typed inputs, and typed outputs:
function normalizeSystemId(systemId: string): (normalized: string) { return systemId.trim()}On the Board, this becomes a Function layer. systemId is an input boundary pin, normalized is
an output boundary pin, and every call becomes a Call Function node wired to that layer.
The signature is part of the visible graph contract. Renaming, reordering, or retyping a parameter changes a pin. Changing a return changes what callers can consume. All callers share the same implementation.
Use a function when:
- several callers need logic that must remain identical;
- the operation needs a named, typed contract whose internals may change;
- the result should be tested as a unit; or
- the call needs an explicit cache policy.
Do not extract every cluster. A one-off group of nodes may read better inline, especially when its wires explain more than a generic helper name would. Extract it when the boundary clarifies the logic.
Functions are reusable within their Flow. Public APIs, schedules, and agent tools need a triggerable Event boundary; cross-Flow reuse needs a packaged node.
12.2 Execution moves forward; pure data is pulled backward
Section titled “12.2 Execution moves forward; pure data is pulled backward”Flow-Like evaluates in two directions:
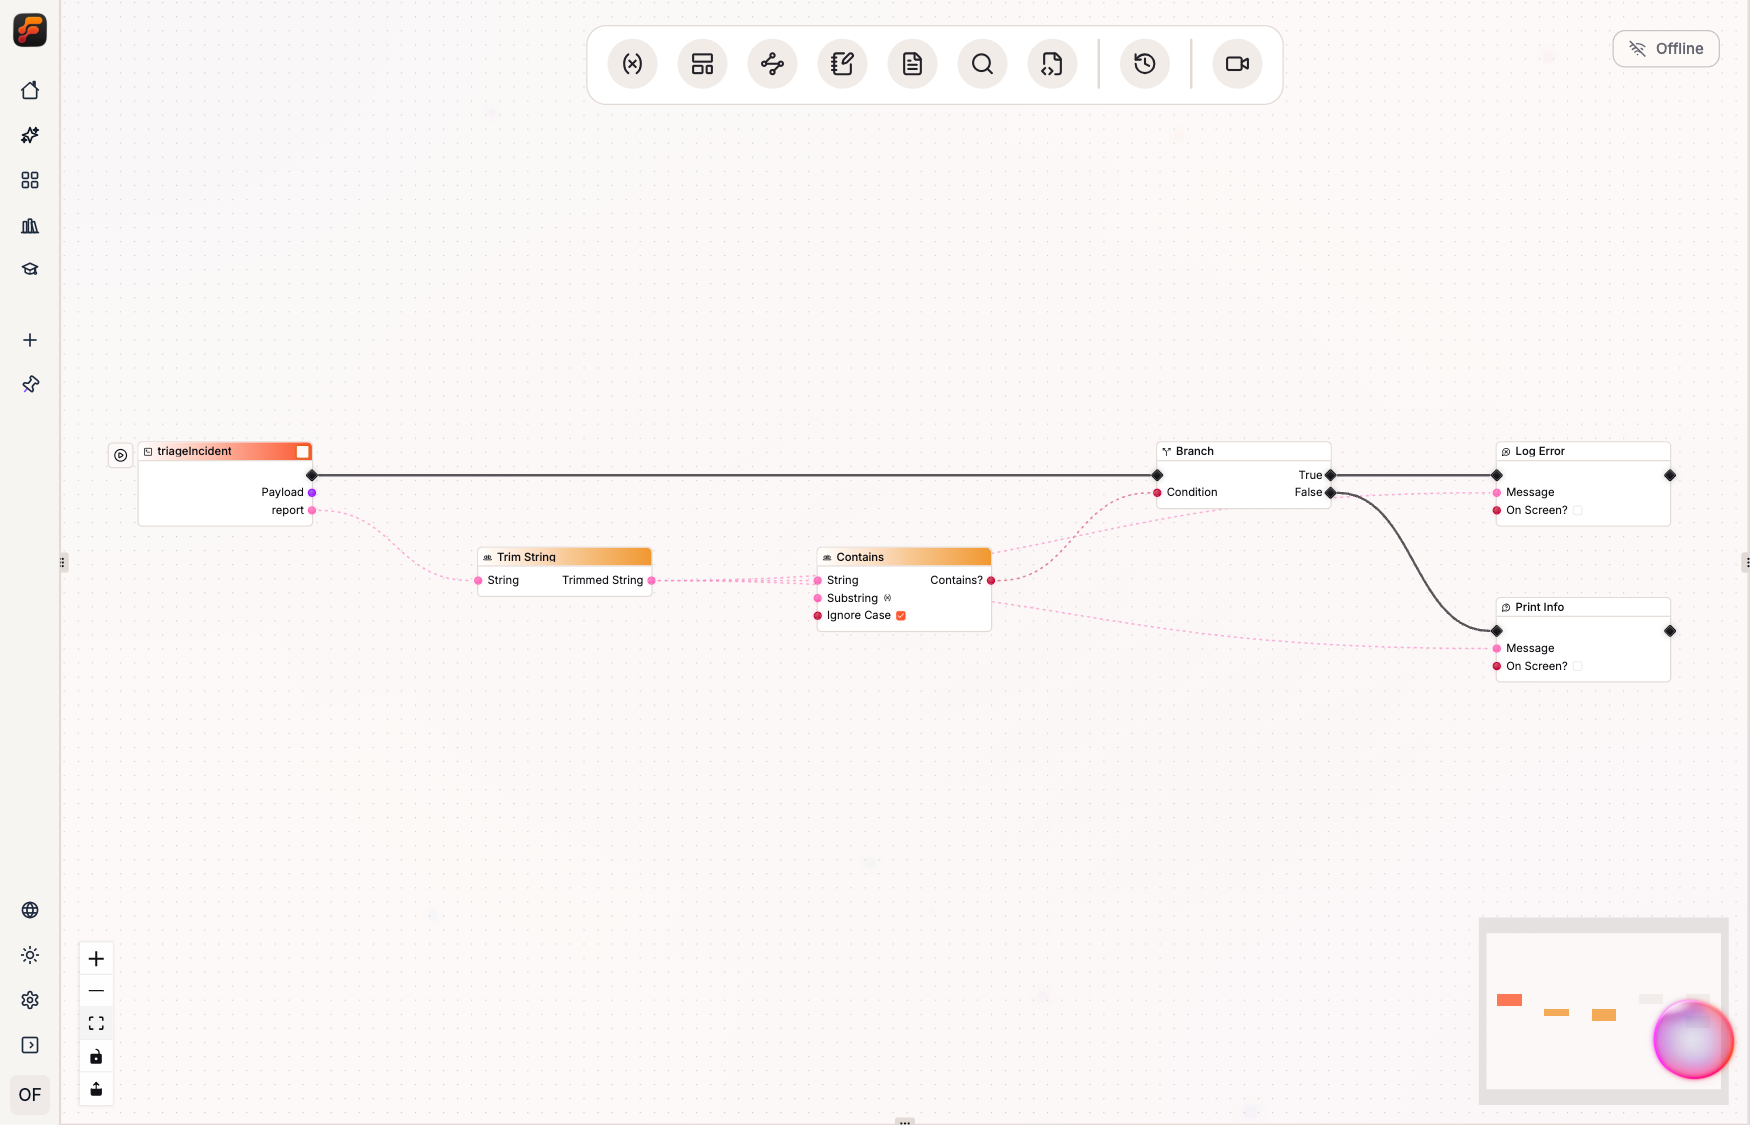
Execution travels forward through Execution pins. Before an impure node runs, the runtime walks backward through any pure data dependencies, evaluates them in dependency order, then runs the consumer.
This gives an apparently small rule a large consequence:
An unused pure value performs no work.
If systemId.trim() reaches no return pin or executing consumer, it does not run. An impure call on
the execution chain does run even when nobody uses its data output.
Who decides purity?
Section titled “Who decides purity?”The node designer does. The runtime uses this structural test:
| Node shape | Runtime classification |
|---|---|
| No Execution pins | Pure, evaluated when data is demanded |
| One or more Execution pins | Impure, scheduled through execution flow |
That structure is a promise. The engine does not inspect Rust or WASM code to prove determinism or the absence of side effects. Hiding a network request or mutation behind a pure data pin breaks the execution model.
For node authors:
- make inexpensive deterministic transformations pure;
- make state-changing operations impure;
- usually make expensive work impure so its cost and schedule stay visible.
FlowScript derives a Function layer’s execution shape from its body. An impure call, Board variable write, branch, or loop gives the Function execution boundary pins. A function containing only pure data dependencies and declared returns can remain pull evaluated.
“Deterministic” and “structurally pure” differ. The cached resolveSystem example contains an if.
Its result is deterministic and side-effect-free, yet the planner represents its branch with
execution flow, making the Function structurally impure.
The Unreal Engine comparison
Section titled “The Unreal Engine comparison”Blueprint authors will recognize the model. Epic’s official Functions documentation defines a Blueprint Pure function by its promise not to modify state. Impure functions are placed on explicit execution wires; pure functions are evaluated when a connected consumer needs their data. Epic also warns in its UFunctions documentation that pure functions do not cache their results, making non-trivial work a performance concern.
Flow-Like uses the same split between explicit execution and demand-driven data. If operators need to see when and where an expensive calculation runs, mark it impure even when it does not mutate state.
Purity answers when is this data needed? Caching answers may an older result replace this call?
12.3 Every user function has a receiver
Section titled “12.3 Every user function has a receiver”Every user-defined function with at least one parameter can be written as a method on its first argument:
const normalized = normalizeSystemId(systemId)const sameValue = systemId.normalizeSystemId()Both forms call the same Function layer. In method form, systemId fills the first parameter and
the remaining arguments follow:
const { team, runbook } = normalized.resolveSystem(directoryRevision)This works for every user function with a first parameter. Its type gives the editor an unambiguous
receiver contract for suggestions after receiver..
Method syntax is call sugar over the same pins. It does not imply object ownership, receiver mutation, or a different runtime. Board-to-source projection may normalize it back to a flat call, so the spelling is not yet preserved across a round trip.
For catalog nodes, the designer selects a receiver pin in catalog metadata, with a limited first-data-input fallback for compatible namespaces. Having an input alone does not make a catalog node a method.
12.4 Functions are reusable; Events are triggerable
Section titled “12.4 Functions are reusable; Events are triggerable”A function has a typed call boundary and no independent runtime entry. An agent needs an Event to trigger it.
Any suitable Event can be registered explicitly as a tool. When the reusable logic lives in a function, a thin Event shim supplies the trigger boundary:
eventsGeneric configureIncidentAgent(payload: Struct, agent: Struct, directoryRevision: string) { const configuredAgent = agent::registerFunctionTools({ agentIn: agent, tools: [resolveSystemTool], }) eventsGeneric resolveSystemTool(systemId: string) { const normalized = systemId.normalizeSystemId() const { team, runbook } = normalized.resolveSystem(directoryRevision) return { team: team, runbook: runbook } } return configuredAgent}tools: [resolveSystemTool] is reference metadata rather than an array passed through a data pin.
It records the concrete handler the agent may invoke. The nested handler remains an independent
Event entry. Its parameters become inferred tool input properties; its return becomes the result.
The model-facing schema describes those properties, but does not mark them required or advertise a declared output schema. The handler must validate its inputs.
Today, the author must write this handler. Registering resolveSystem directly fails because a
Function layer has no trigger node. A future convenience may generate the shim while leaving the
Event and registration visible.
Tool registration accepts referenceable Event entries, including the supported Simple, Generic, Chat, and Widget Action entries. It does not accept every start node. Registering an Event for an agent does not expose a public API; Chapter 13 covers that boundary.
Tool schemas are inferred; policy remains authored. Function references carry no confirmation, allowed-caller, cost-limit, or permission object. Put required confirmation or domain authorization inside or next to the handler. Package capabilities and runtime permissions still apply.
12.5 @cache is an authored promise
Section titled “12.5 @cache is an authored promise”Flow-Like never silently decides that a function should be cached. The author opts in visibly:
@cache({ namespace: "incident-system-directory-v1", ttlSeconds: 600 })function resolveSystem(systemId: string, directoryRevision: string): (team: string, runbook: string) { let team = "platform-on-call" let runbook = "runbooks/general.md" if (systemId == "payments") { team = "payments-on-call" runbook = "runbooks/payments.md" } return team, runbook}A cache hit replaces the complete call. The runtime restores the named outputs, activates the continuation, and skips every node in the function. Side effects in the body do not happen.
That leads to the safe contract:
Cache a function only when the same declared inputs may legitimately reuse the same outputs for the chosen freshness window, and skipping the entire body is correct.
The engine trusts the author. Apply permits caching a structurally impure function, though the UI can warn. This may suit an expensive read or deterministic branch. Do not cache behavior that must occur on every call, such as a write, notification, or audit entry.
What forms the key today
Section titled “What forms the key today”The effective function-cache identity is:
App + scope + user when user-scoped + namespace + hash(Function layer ID + successfully evaluated input names and values)Object keys are canonicalized; array order is preserved. The stable Function layer ID prevents functions in one namespace from sharing entries.
The following are not included automatically:
- the function body or output contract;
- catalog, package, or WASM-node versions;
- Flow globals and runtime variables;
- secrets or provider profiles;
- model selection;
- deployment configuration; and
- database, file, or external API state.
If one changes the legitimate result, expose its identity or revision as an input, or invalidate or
version the namespace. That is why the example accepts directoryRevision.
Bare @cache currently means namespace global, a five-minute lifetime, and App scope. The visual
Function editor has different defaults, including no expiry. Until the editors converge, the book
uses a settings object with an explicit namespace and TTL. App scope is omitted because it is the
FlowScript default. Reserve ttlSeconds: 0 for entries with an invalidation and cleanup plan.
When the cache backend or entry is unavailable, the runtime warns and executes the function. Cache writes are best-effort. Concurrent identical misses are not combined, so the cache provides neither distributed locking nor exactly-once behavior.
12.6 Invalidate after the source of truth changes
Section titled “12.6 Invalidate after the source of truth changes”Namespaces give related entries one invalidation boundary. Open the same scope and namespace, then remove the group:
eventsGeneric invalidateSystemDirectory(payload: Struct, directoryRevision: string) { const directoryCache = data::cache::open({ scope: "app", namespace: "incident-system-directory-v1", }) const deleted = directoryCache.invalidateNamespace() log::info({ message: `Revision ${directoryRevision}: invalidated ${deleted} resolution(s)`, toast: false, }) return deleted}Run this Event after a successful authoritative directory update, never after each read. The order is:
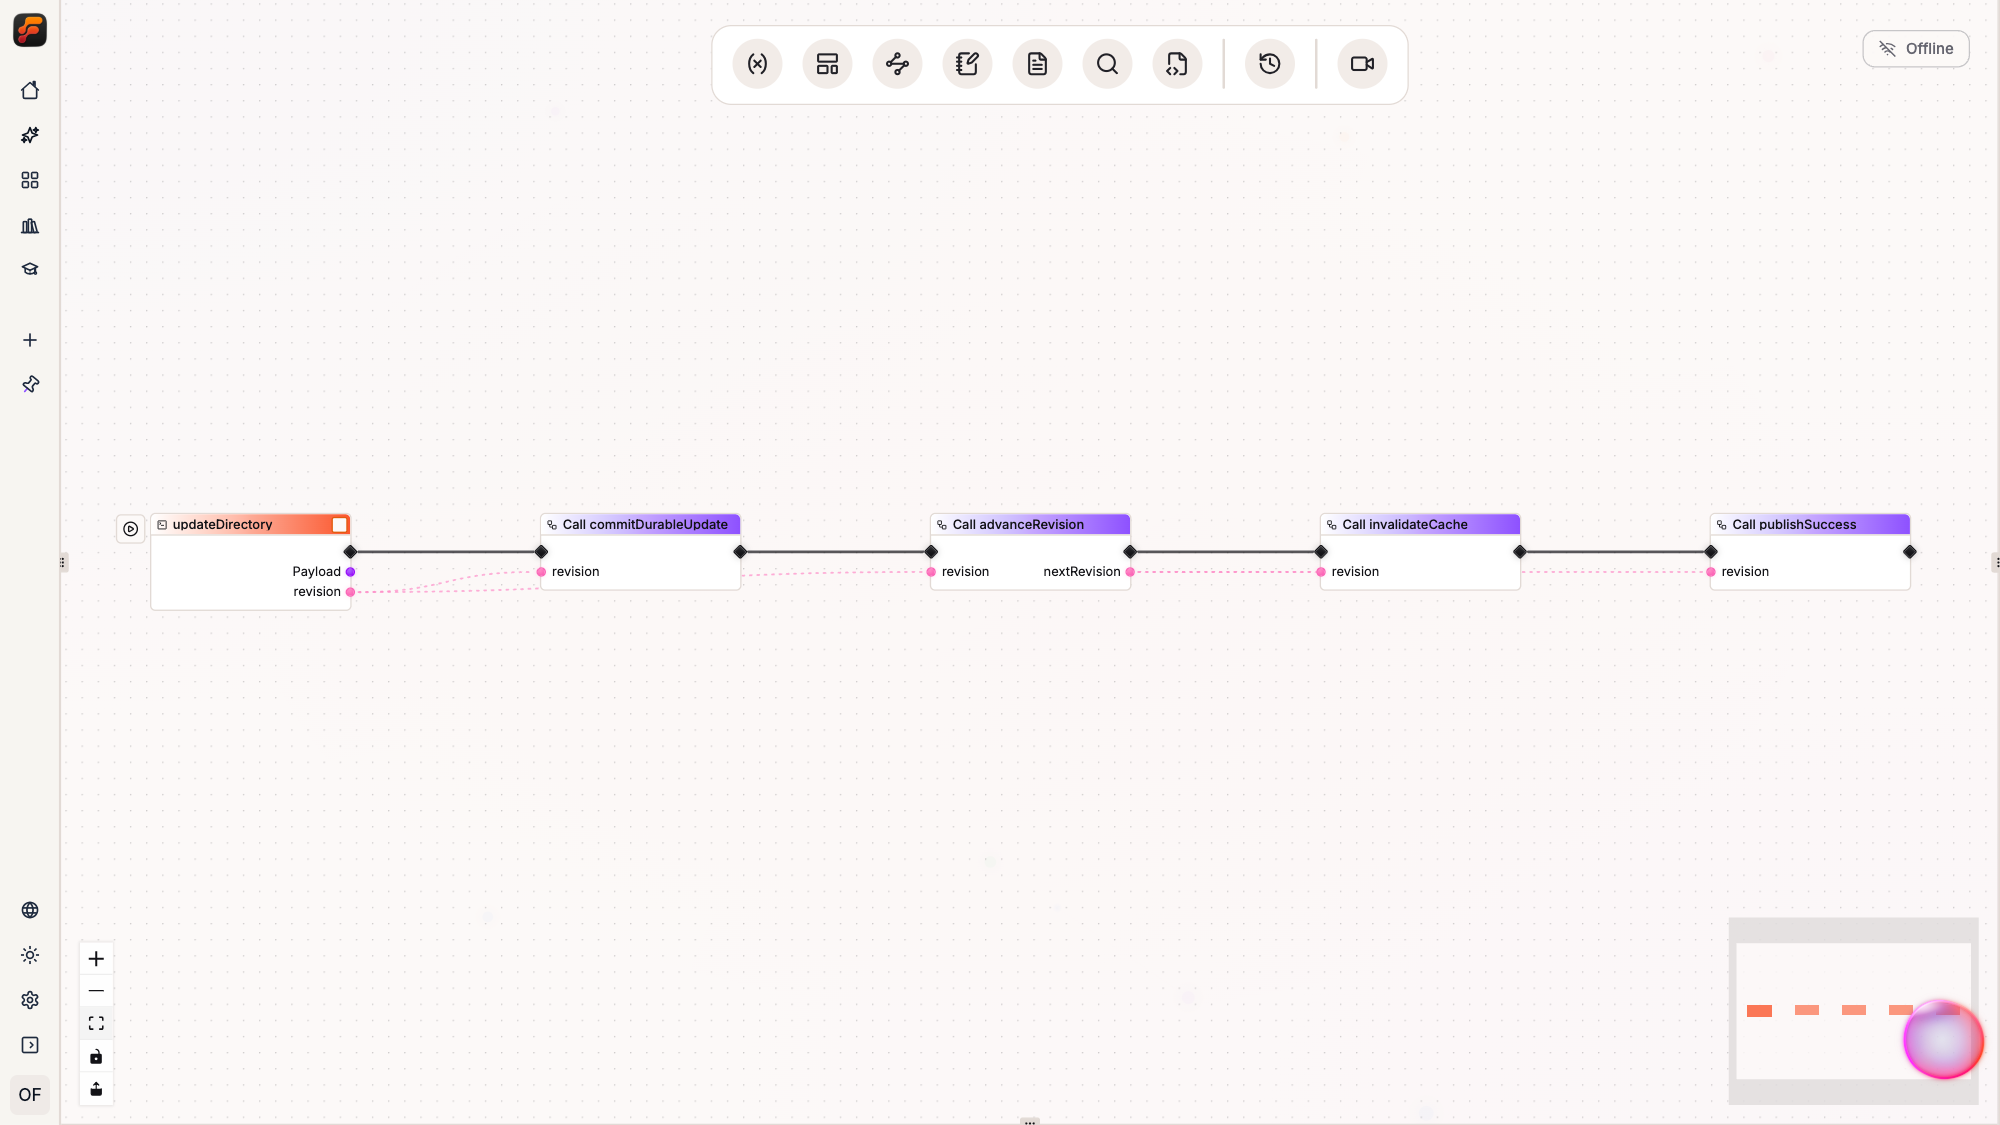
A lookup that missed before invalidation can finish afterward and write an old result back. Passing
directoryRevision prevents new callers from using that key. Versioning the namespace also
isolates it, though old entries remain until TTL or cleanup removes them.
Code, return names, package versions, model choice, and configuration do not clear cached results. Invalidate them when such a change alters the answer.
12.7 Use layers for readability, functions for sameness
Section titled “12.7 Use layers for readability, functions for sameness”An ordinary layer collapses part of one graph into a named nested view. Use one to reduce canvas clutter, label a section, or sketch a placeholder.
A Function layer changes the relationship:
| Situation | Prefer |
|---|---|
| One inline section is visually noisy | Ordinary layer |
| A placeholder sketches work to implement later | Ordinary layer |
| Copies are intended to remain the same | Function |
| Several callers need one typed contract | Function |
| Results should use automatic function caching | Function |
| A caller or agent must trigger the logic independently | Event, usually wrapping a function |
Studio can convert a suitable collapsed layer into a Function. It preserves the inner nodes and typed boundary pins, then replaces the inline occurrence with a Call Function node.
Similar blocks may encode intentionally different policies. Extract them only when a change to one must be repeated in the others.
12.8 Read the complete function and cache example
Section titled “12.8 Read the complete function and cache example”The canonical Chapter 12 fixture combines the chapter’s boundaries:
function normalizeSystemId(systemId: string): (normalized: string) {    return systemId.trim()}
@cache({ namespace: "incident-system-directory-v1", ttlSeconds: 600 })function resolveSystem(systemId: string, directoryRevision: string): (team: string, runbook: string) {    let team = "platform-on-call"    let runbook = "runbooks/general.md"    if (systemId == "payments") {        team = "payments-on-call"        runbook = "runbooks/payments.md"    }    return team, runbook}
normalizeSystemId is pure and runs when a consumer needs normalized. The visible if makes
resolveSystem structurally impure, but caching is safe because its inputs fully determine the
side-effect-free result, including the directory revision.
The in-source mapping stands in for a governed production directory lookup. The fixture calls both Functions, adapts them through an agent Event, and invalidates the namespace after a durable update.
A function can unify shared logic, and an Event can expose it to independent callers. Add caching only when the runtime may safely skip the whole call.